Tag Archives: ai

Purview’s Limits Are Your Cost and Risk Problem

By Chas Meier

Last week, John Patzakis explained why Microsoft Purview eDiscovery is getting worse and why the reasons are structural: a multi-tenant architecture that must throttle heavy workloads, a 2 GB per hour indexing ceiling that has not moved since 2024, no service level commitment for search times, and a finite pool of compute that Microsoft has told investors it allocates to its highest-value opportunities, with Copilot first in line.

That post was about the cause. This one is about the consequence, and it is a consequence that reaches well beyond legal operations. When the tool at the front of your eDiscovery workflow cannot filter reliably, the organization’s answer is almost always the same: collect everything and sort it out later. Every gigabyte that leaves your environment that way is a gigabyte you pay to process, host and review, and a gigabyte that now sits somewhere you do not control, at exactly the moment attackers are becoming faster and better equipped than they have ever been.

The argument below is simple. Purview’s limits drive over-collection. Over-collection drives cost. Cost and copies drive risk. And the risk curve is about to steepen.

When Filtering Fails, Over-Collection Becomes the Default
In principle, Purview lets you search before you collect. In practice, the service providers and enterprise teams we speak with tell us that targeted collection in Purview has become something they plan around rather than rely on.

  • Searches stall or time out.
  • Indexing runs at 2 GB per hour, so a 500 GB custodian set takes more than ten days to index before a search can be trusted.
  • Partially indexed items that exceed parsing limits quietly fall outside keyword results.
  • Exports are capped at 2 GB per hour per mailbox with daily tenant-level limits, and anything still running after seven days is cancelled.

Faced with a deadline and a toolset that cannot be trusted to narrow the data defensibly, legal teams do the rational thing: they widen the net. Rather than risk a motion over an under-inclusive search, they pull entire mailboxes, entire OneDrive accounts, entire Teams channels, and push the filtering downstream to a processing platform or a service provider where the tools actually work. One provider described it to us as “collect the custodian, not the matter.”

This is not a failure of judgment by the legal team. It is the predictable response to a collection tool that cannot do its job at enterprise scale. But it means that the single most effective cost and risk control in eDiscovery, culling data before it ever leaves the enterprise, is being abandoned at the very step where it matters most.

Not a Purview User? You Probably Are One Anyway
Many organizations read our Purview posts and conclude they do not apply because the legal team never logs into the Purview portal. They use a service provider, or a collection toolkit from their review platform vendor, or a connector that “just pulls from Microsoft 365.” That conclusion is usually wrong.

Look under the hood of most Microsoft 365 collection workflows and you find Purview. Many third-party connectors and service provider toolkits are built on Microsoft’s eDiscovery search and export APIs, which means they inherit the same index, the same 2 GB per hour ceilings, the same tenant-level export caps and the same throttling. Some tools run a Purview search and export in the background and present the result in their own interface. Others collect whole mailboxes through Graph or EWS precisely because the Purview search path is too slow and unreliable to filter with, which is over-collection by design. Either way, Purview’s limitations are shaping what gets collected from your tenant, even if nobody on your team has ever opened it.

If you are not sure which category your workflow falls into, that is worth finding out. Ask your provider or your platform vendor two questions:

  1. Does your Microsoft 365 collection depend on Purview’s index or Microsoft’s eDiscovery APIs?
  2. What percentage of the data you collect from our tenant is ultimately produced?

If the first answer is yes and the second answer is in the low single digits, you are an indirect Purview user, and you are paying for it.

The Volume Does Not Disappear. It Moves Downstream.
Data that is not filtered at collection does not go away; it flows into the next stage of the workflow. Whole-custodian collections land on a service provider’s processing infrastructure or in a hosted review platform, where the filtering that should have happened inside the enterprise is finally performed, at a per-gigabyte price. The industry has become very good at absorbing that volume, which is part of why the problem is so easy to ignore. Processing gets faster, hosting gets cheaper per unit, and analytics get better at culling. But none of that changes the fact that the data has already left.

The numbers compound quickly:
• A matter with 20 custodians and an average of 30 GB per custodian across email, OneDrive and Teams produces 600 GB of exfiltrated data before a single document has been reviewed.
• A targeted in-place search would have narrowed that to 5%; the other 570 GB is pure overhead: ingested, processed, deduplicated, and hosted for the life of the matter, and then for years afterward.
• Multiply that across every matter, investigation and regulatory request in a year and the over-collection tax on a mid-size enterprise runs into the hundreds of thousands of dollars, and for a large one, well into the millions.

Service providers see the other side of this. Their platforms are filling with data that nobody needed, and their clients are increasingly asking why the processing and hosting line items keep growing when case counts are flat. The honest answer: the collection tool upstream stopped doing its job.

Every Exfiltrated Gigabyte Is Both a Cost and a Risk
The cost side is visible on the invoice. Processing, hosting, review, productions and long-tail storage all scale with volume, and over-collection inflates every one of them. What is harder to see is that the same volume is also the organization’s single largest self-inflicted security exposure.

Consider what an eDiscovery collection actually is: a curated copy of your most sensitive communications, deliberately assembled, stripped of the access controls that protected it in the source system, and shipped to a third party. Executive email. Board materials. Privileged legal advice. Customer data, employee data, trade secrets, M&A deliberations. A whole-custodian collection does not just include the documents relevant to the matter; it includes everything that custodian ever touched. And it is now sitting on a service provider’s processing server, in a hosted review platform, in a law firm’s document management system, on an export drive, and in whatever backups each of those parties keeps.

Each copy is a new attack surface governed by someone else’s security program, someone else’s patch cycle and someone else’s employees. Law firms and eDiscovery vendors are high-value targets precisely because they aggregate the crown jewels of many clients in one place, and the breach record of the last several years bears that out. When one of those copies is compromised, the breach notification obligations, regulatory exposure and reputational damage belong to you, not to the vendor, and they attach to all of the data that was collected, not just the small fraction that was ever relevant.

Over-collection, in other words, turns a legal cost problem into an enterprise security problem. The 95% of the collection that was never responsive was never worth that risk.

The Next 12 to 24 Months: AI on the Other Side of the Wall
If the risk calculus above were static, over-collection might be a tolerable inefficiency. It is not static. The same generative AI wave that is consuming Microsoft’s compute capacity is also arming the people who want your data.

AI has collapsed the cost and skill required to run a sophisticated attack. Phishing campaigns are now fluent, personalized and generated at scale. Vulnerability discovery and exploit development that once took skilled teams weeks can be accelerated by models that reason over code. Reconnaissance against a target’s vendors, employees and infrastructure is automated. Agentic tooling allows a single operator to run many intrusion attempts in parallel and adapt to defenses in real time. Security researchers and government agencies have been warning for the past year that AI-enabled intrusion is moving from proof of concept to routine practice, and the trend lines for breach frequency, ransomware payouts and time-to-exploit all point the same way.

Over the next 12 to 24 months, we expect frequent, aggressive and automated attacks to become the baseline rather than the exception, and we expect the organizations that aggregate other companies’ sensitive data, including eDiscovery service providers, review platforms and law firms, to remain among the most attractive targets. Vendors will keep investing in defenses. But a defender has to be right every time, and AI has made the attacker’s job dramatically cheaper.

The only exposure you fully control is the amount of data you send out in the first place. Every copy you do not create is a copy that cannot be breached.

Now Is the Time to Be Proactive
The organizations that will be in the strongest position two years from now are the ones that treat eDiscovery collection as a data governance and security decision, not just a legal workflow step. That means three things.

  • Limit exfiltration. Search, cull and validate inside your own environment, and collect only what is potentially responsive. The goal is to move the filtering step back to where it belongs, before the data leaves, so that what reaches a provider or a review platform is the matter, not the custodian.
  • Limit unnecessary cost. Every gigabyte you keep inside the enterprise is a gigabyte you do not pay to process, host, review and store. Targeted in-place collection is the single largest lever available to reduce eDiscovery spend, and it is a lever that most Microsoft 365 organizations are not currently pulling because their tooling does not let them.
  • Remain in control of your data. Run eDiscovery and governance on infrastructure you control, with search methodology you can test and document, indexes you own, and no dependence on a shared tenant’s throttling policies or a cloud provider’s capacity priorities. Control means being able to answer a court, a regulator or a board with confidence about what you searched, what you collected and where it went.

Waiting for Purview to improve is not a strategy. Last week’s post explained why its limitations are architectural and why Microsoft’s own capacity constraints make relief unlikely. Meanwhile the cost of over-collection accrues on every matter, and the risk of each unnecessary copy grows with every advance in offensive AI. The time to change the workflow is before the next large matter, not after the next breach.

How X1 Enterprise Is Different
X1 Enterprise was built for exactly this problem: search and collect in place, so that only what matters ever leaves. The differences from a Purview-dependent workflow are architectural, not cosmetic.

In-place indexing you own. X1’s patented distributed micro-indexing technology indexes Microsoft 365 data where it lives, across Exchange, OneDrive, SharePoint and Teams, alongside endpoints, file shares and other cloud sources. X1 does not use Purview’s index or Microsoft’s eDiscovery search APIs, so there is no 2 GB per hour ceiling, no tenant-level export cap, no seven-day cancellation and no throttling inherited from every other tenant on the platform.

Compute you control. X1 runs on infrastructure the customer controls, on premises or in the customer’s own cloud. Your eDiscovery and governance jobs are never queued behind Copilot or anyone else’s workload, and performance is predictable because it is yours.

Search that meets the courts’ standard. Full Boolean, proximity, wildcard and stemming queries execute consistently across email, files and Teams chat, with the ability to iteratively test, refine, validate and document search methodology before anything is collected. That is the “advanced and thoughtful” search the Kim v. Cushman & Wakefield court said Teams data requires, and the validation Special Master Favro found missing in native Microsoft 365 tools.

Targeted collection, not whole-custodian export. Because the search runs in place and can be trusted, only potentially responsive data is collected. Filtering moves back to the front of the workflow, where it cuts downstream volume, cost and exposure at the source. Collected data can be uploaded directly into Relativity for review.

Defensibility by design. Preservation, search and collection are logged and reportable, so you can show a court or a regulator exactly what was searched, when, with what criteria, and what was collected.

AI where the data lives. The same in-place architecture powers X1 AI In-Place, allowing organizations to apply AI classification directly to data in its source location for early case assessment, privilege and sensitivity identification, and information governance, again without exporting the data to do it.

Talk With X1
If your Microsoft 365 collections are coming back as whole custodians, if your processing and hosting invoices keep growing while your case count does not, or if you have never asked how much of the data you send out is actually responsive, we would like to talk.

Contact X1 to schedule a live demonstration of X1 Enterprise against a Microsoft 365 environment. Better still, bring us a recent matter. We will run a targeted in-place search on your own data and show you how much volume, cost and risk you could have kept inside the enterprise.

The next large matter is coming, and so is the next wave of attacks. Collect less, spend less and keep control of your data.
Leave a comment

Filed under AI In-Place, Best Practices, Cloud Data, Corporations, Cybersecurity, Data Governance, ECA, eDiscovery, eDiscovery & Compliance, Enterprise AI, Enterprise eDiscovery, ESI, GDPR, Information Governance, Information Management, m365, MS Teams, OneDrive

Microsoft Purview eDiscovery Problems Are Structural—and Growing

By John Patzakis

For organizations that rely on Microsoft Purview for eDiscovery, compliance and investigations, the gap between what the tool delivers and what the job demands is widening. Stalled searches, timed-out exports and a 2 GB per hour indexing cap slow investigations, drive up costs and leave legal teams with results they can’t fully defend.

Over the past several months, we have been speaking with a number of eDiscovery service providers, channel partners, and enterprise customers about their experiences with Microsoft Purview eDiscovery. The feedback has been remarkably consistent. The same challenges we began writing about several years ago are still there, and by most accounts they have gotten worse. One service provider that handles a high volume of Microsoft 365 matters told us that Purview performance has deteriorated noticeably in recent months, describing searches and exports that stall or time out and processing delays that have put counsel in a difficult position with opposing parties and the court.

When X1 first raised these issues, the common reaction in the market was that Purview was a maturing product that Microsoft would eventually fix. With Microsoft’s engineering resources, many assumed that eDiscovery inside Microsoft 365 would steadily improve. That was a reasonable expectation at the time. It has not happened. In our view, the reason is that Purview’s limitations stem from the architecture of Microsoft 365 itself, which makes it very difficult to engineer away. And there is now an additional factor worth considering: the intense competition for computing resources driven by Microsoft’s AI strategy.

The Architecture Has Not Changed
As we explained in our post on Microsoft 365 eDiscovery throttling, Microsoft 365 is a massive multi-tenant SaaS environment. Every customer shares pooled infrastructure, and eDiscovery is exactly the kind of heavy, bursty workload that a multi-tenant system must restrain to protect everyone else on the platform. Throttling, timeouts, and hard caps are how Microsoft manages that “noisy neighbor” problem, and they are built into the design of the system. We made the same point more broadly last December in our analysis of why most SaaS architectures fall short for enterprise-grade AI: shared capacity introduces contention and performance variability that no configuration setting can resolve.

Microsoft’s own documentation bears this out. The current Microsoft Learn page on eDiscovery limits, last updated in June 2026, shows:

  • 2 GB per hour for advanced indexing in Purview eDiscovery Premium. That is the same cap we cited in 2024. At that rate, indexing a single terabyte requires roughly three weeks of continuous processing.
  • 2 GB per hour per mailbox limit for exports, with daily exports capped at the tenant level.
  • Automatic cancellation of any process or export still running after seven days.
  • No service level agreement for search terms. Microsoft also states plainly that it “doesn’t provide a service level agreement for search times.”

Microsoft even maintains a service advisory to notify administrators when their tenant has been “throttled due to number of Search and Export jobs exceeding the limit set by Microsoft.”

For organizations with significant information governance requirements, these constraints are even more limiting. As we discussed in our post on information governance challenges in Microsoft 365, a defensible governance program depends on automated enforcement across the full data estate, and a 2 GB per hour ceiling makes that impractical at enterprise scale.

Special Master Favro’s Findings Still Hold
In July 2023, Special Master Philip Favro issued a report in Deal Genius, LLC v. O2COOL, LLC, No. 21 C 2046 (N.D. Ill.), raising serious concerns about whether reliance on Microsoft 365’s native search tools satisfies the reasonable inquiry requirement of Federal Rule of Civil Procedure 26(g). As we reported at the time, the Special Master found that M365 has “technological limitations that may not allow a responding party to generate reliable search results,” that it “generally does not fully index the data” in an organization’s environment, and that it does not allow users to validate their search and production results.

More than three years later, nothing in Microsoft’s documentation indicates those problems have been resolved. The indexing ceiling is unchanged, items that exceed parsing limits are still marked as partially indexed, and there is still no service level commitment. Meanwhile, the courts have raised the bar. In Kim v. Cushman & Wakefield U.S., Inc., 2026 WL 1353455 (C.D. Cal. Apr. 24, 2026), the court held that “[k]eyword searches alone, without more advanced and thoughtful search techniques, will be inadequate for Teams data.” That is a difficult standard to meet with a native toolset built around basic keyword and condition searching.

Recent Developments Reinforce the Concerns
Several developments over the past year add to the picture.

A systemic Purview hold failure. In Oakley v. MSG Networks, Inc., 792 F. Supp. 3d 394 (S.D.N.Y. 2025), Madison Square Garden placed a legal hold through Purview that was intended to ensure emails were “retained no matter what the user does.” Emails from eleven custodians were lost anyway. MSG’s forensic expert concluded that a technical glitch in its Microsoft environment had occurred “beyond a shadow of a doubt,” and the court noted that “the software malfunction affected seventy-nine matters other than the Oakley case.” MSG avoided sanctions because the court found its use of Purview to be a reasonable preservation step. But the emails were gone, and MSG had to fund a forensic investigation and litigate the issue to establish it was not at fault. Reasonableness under Rule 37(e) turns on what a party knew or should have known, and as the record of Purview failures grows, I would not count on that defense being available indefinitely.

Sanctions for delay even when reliance was reasonable. In FTC v. Match Group, Inc., 2025 WL 46024 (N.D. Tex. Jan. 7, 2025), an archiving system used with Office 365 failed to capture certain custodians and time periods. Match produced nearly 500 additional documents after the discovery deadline, most of them after the FTC had moved for summary judgment. The court found Match’s reliance on the archive reasonable, yet still imposed sanctions under Rule 16(f) for the late production, allowing the FTC additional depositions at Match’s expense. The lesson for Purview users is clear: courts can and will sanction delays caused by collection tools, regardless of how reasonable the choice of tool may have been.

Reduced functionality. In 2025 Microsoft moved all customers to its new Purview eDiscovery experience, retiring classic Content Search and eDiscovery (Standard) in May and classic eDiscovery (Premium) in August. In the process, Microsoft retired its legacy legal hold communications tools for custodian notices and acknowledgments. And as Casepoint has noted, the new interface no longer shows that a custodian was ever on hold once that custodian is released, making it harder to document a preservation timeline. The visibility problem is significant enough that a new third-party reporting product launched this spring because, as LawNext reported, legal teams have “no direct visibility into what is happening inside Microsoft Purview eDiscovery.”

More data, more complexity, new fees. Copilot is generating entirely new categories of data that Purview must preserve, search, and produce. Microsoft recently had to add an option to convert Loop and Copilot Pages files to HTML because those formats cannot be opened by standard review tools. Microsoft now also bills pay-as-you-go storage for certain AI interaction data in eDiscovery cases and requires E3 customers to activate pay-as-you-go billing to use its eDiscovery export APIs.

Service disruptions. On January 22, 2026, an infrastructure failure in North America blocked administrator access to the Purview portal, along with Exchange, Teams, and SharePoint search, for several hours.

The AI Factor
This brings us to a question several of our partners have raised with us. Microsoft has been unusually candid with investors that it does not have enough computing capacity to meet demand, and that it is making deliberate choices about where that capacity goes.

On Microsoft’s January 28, 2026 earnings call, CFO Amy Hood described the order of priority directly: “the first thing we’re doing is solving for the increased usage in sales and the accelerating pace of M365 Copilot. Then we make sure we’re investing in the long-term nature of R&D and product innovation,” with “the remainder going towards serving the Azure capacity that continues to grow in terms of demand.” She added that if the GPUs that came online in the prior two quarters had been allocated entirely to Azure, Azure’s growth metric “would have been over 40” percent.

On the October 28, 2026 call, Ms. Hood reported that “[c]ustomer demand continues to exceed available supply.” CEO Satya Nadella said Microsoft will “dynamically allocate capacity to the highest-value opportunities across compute, data, Foundry, and Copilot,” explaining that “we have one pool, and we want to get the pool to be as efficient and fungible” as possible. Microsoft is now projecting capital spending on the order of $170 billion to try to catch up.

Microsoft has not said where Purview eDiscovery falls in that order of priority, and we have no inside view into how Microsoft allocates resources within its data centers. But consider what Microsoft has told us. It operates “one pool” of capacity. That pool is constrained. Capacity is allocated to the “highest-value opportunities,” and Copilot is first in line. eDiscovery is a compliance function that generates little incremental revenue, carries no service level commitment for search times, and has seen its documented throughput limits stay frozen while its feature set has been trimmed. At the same time, Copilot is adding new volumes and types of data that Purview is expected to handle.

When capacity is scarce and allocated by value, it is fair to ask how high a priority eDiscovery search and export jobs receive. The service providers and customers telling us that Purview has gotten worse may be seeing the practical result of that ordering. Organizations planning their discovery and governance obligations around Purview should at least account for that possibility.

A Different Architecture
X1 takes a fundamentally different approach. The X1 Enterprise Platform uses our patented distributed micro-indexing technology to index Microsoft 365 data in place, across Exchange, OneDrive, SharePoint, and Teams, along with endpoints, file shares, and other cloud sources.

For legal and compliance teams, that means:

  • Predictable timelines. X1 does not depend on Purview’s search index or Microsoft’s eDiscovery search APIs, so it is not subject to Purview’s indexing ceiling, export caps or the throttling that comes with sharing those resources with every other Microsoft tenant.
  • No competing with Copilot for capacity. The compute runs on infrastructure our customers control, which means eDiscovery and governance jobs are not competing with Copilot for priority.
  • The search methodology courts now expect. Full Boolean, proximity, wildcard, and stemming queries that execute consistently across email and Teams chat, with the ability to iteratively test, validate and document search methodology before anything is collected.
  • Lower cost and less risk. Only potentially responsive data is collected, and it can be uploaded directly into Relativity for review.
  • AI where your data lives. The same in-place architecture powers X1 AI In-Place, allowing organizations to apply AI classification directly where their data lives without the cost, delay, and exposure of moving it.

X1 works alongside your Microsoft 365 investment. Your data stays in M365, and X1 gives you the defensible, scalable discovery layer Purview wasn’t built to provide.

If your organization or your clients are running into these issues with Purview, we would like to hear from you. Contact X1 to schedule a live demonstration of X1 Enterprise in a Microsoft 365 environment, or to discuss a proof of concept on your own data.

Leave a comment

Filed under AI In-Place, Best Practices, Cloud Data, Corporations, Data Governance, eDiscovery, eDiscovery & Compliance, Enterprise AI, Enterprise eDiscovery, ESI, Information Access, Information Governance, Information Management, m365, MS Teams

The AI Token Bill Comes Due: Why Enterprise Search Is the Hidden Driver of AI Cost — and How to Fix It

By John Patzakis

A graphic illustrating the blog title 'The AI Token Bill Comes Due: Why Enterprise Search Is the Hidden Driver of AI Cost — and How to Fix It'. It features a funnel shape with icons representing email, chat, and files, surrounded by digital elements and a blue background.

For two years, the enterprise conversation about AI was about capability: What can it do? Is it good enough? In 2026, that conversation changed almost overnight. The question now is the bill. Alexander Embiricos, who leads enterprise at OpenAI, put the shift plainly to TechCrunch in June: “Six months ago, I would have a conversation with a customer, and it would be all about ‘What can it do?’ Our conversations are never about that now. Now the conversations are about, ‘hey, we’re spending so much. What visibility do you have?…What token controls do you have? What is the efficiency of your models?’”

Anthropic — the maker of Claude — identifies inefficient retrieval as a primary culprit in its own engineering writing. In its November 2025 piece on advanced tool use, Anthropic describes the failure mode directly: when an agent fetches records across a data set, “every record accumulates in context regardless of relevance,” and when a large file is retrieved, “the entire file enters its context window.” Independent analysts reach the same conclusion. A June 2026 study measured a 26x per-query token gap between dumping full documents into context and retrieving selectively. A DeployStack analysis traced a routine two-step document workflow that “consumed 120,000 tokens” because a single file passed through the model twice, warning: “Run this 100 times a day across a team, and you’re looking at real money.” And Dennis Pilarinos of Unblocked names the specific culprit without hedging:

“Broad search is the default failure mode, and it’s the most expensive one.”

— Dennis Pilarinos, Unblocked

Enterprise search is the textbook worst case
Nowhere does this dynamic bite harder than search over large, unstructured stores — email inboxes, file shares, chat archives, document repositories. When an employee asks Claude to “find everything about the Henderson matter” or “pull the emails where we discussed pricing,” a single query can drag hundreds of matching messages, long threads, and full attachments into the context window as raw payload. The user pays for all of it, every time — even though only a handful of items actually mattered. The larger the store and the broader the query, the worse the ratio. And broad, unfiltered search over massive stores is exactly how people naturally use these tools.

The fix is architectural: search in place, then bring only what matters
If token cost is driven by data flowing through context, the highest-leverage optimization for enterprise search is not a spending cap — it is a change in architecture. Locate first; retrieve selectively. Search the data where it lives, then bring only the relevant results into the model. A design that returns a ranked result list, targeted snippets, and a pointer to the source document — rather than dumping full inboxes and file bodies into context — attacks the cost problem precisely where the evidence says it lives. This is, notably, the same conclusion Anthropic’s own engineers advocate.

This is exactly what the new X1 Search MCP Connector for Claude does. X1 maintains a local, enriched index over an organization’s actual content — files, emails, attachments, Microsoft 365, Google Workspace, chats — and searches that content in place, on the user’s own machine or behind the corporate firewall. Exposed to Claude through the Model Context Protocol, X1 returns exactly what the model needs and nothing it doesn’t: a compact ranked result list, targeted snippets, and a file location, instead of streaming entire mailboxes and documents through the context window. Claude then reasons over only the specific items that matter, opening full content on demand for the few documents actually under review. Because the matching happens locally, a query across a massive corpus costs roughly the same handful of tokens whether the index holds a thousand items or a million — and because only relevant results ever leave the machine, the data-exposure footprint shrinks at the same time, preserving confidentiality and privilege for legal, compliance, and government teams.

The ROI
The economics are not marginal. At current large-model rates, a single broad search across a year’s worth of emails or a file share can cost roughly $20 in AI tokens when the raw content is streamed into the model — versus a fraction of a cent when only the relevant results are passed to it. Across an organization with thousands of users searching throughout the day, that difference compounds into millions of dollars in avoided token costs each year, while simultaneously improving response speed and reducing data exposure. The savings scale directly with data volume, which means the connector becomes more valuable — not less — as an organization’s data grows.

The takeaway
The token bill has come due, and every fix now being marketed — observability tools, model routers, usage caps — treats the symptom. Each one helps a company watch its spending or throttle it; none of them changes the fact that, by default, enterprise data has to travel to the AI to be searched, at full token price, every single time. The durable answer is to invert that: bring AI to the data, not the data to the AI. Search in place, return only what matters, and let the model reason over the few items that count. That is not a workaround for the cost problem. It is the architecture the evidence — including the AI providers’ own — points to as the way out.


Sources

  • Anthropic, Introducing advanced tool use on the Claude Developer Platform (Nov 2025) — anthropic.com/engineering/advanced-tool-use
  • Anthropic, Code execution with MCP: building more efficient AI agents (A. Jones & C. Kelly, Nov 2025) — anthropic.com/engineering/code-execution-with-mcp
  • TechCrunch, The token bill comes due: Inside the industry scramble to manage AI’s runaway costs (Jun 5, 2026)
  • DeployStack, How MCP Servers Use Your Context Window (Jan 2026) — deploystack.io
  • Unblocked (D. Pilarinos), Why AI Agents Burn Tokens (Jun 2026) — getunblocked.com
  • The Token Tax of Epistemic Accuracy: Comparing RAG and Long-Context Architectures (arXiv, Jun 2026)

Leave a comment

Filed under Best Practices, Business Productivity Search, Cloud Data, Corporations, Data Audit, eDiscovery & Compliance, Enterprise AI, Enterprise Search, ESI, Google Workspace, Information Access, Information Governance, Information Management, m365

Enterprise AI Has a Token Cost Problem — But It’s Very Fixable. What most AI vendors aren’t telling you.

By Larry Gill

The promise of AI in the enterprise is everywhere right now. Every eDiscovery vendor, legal tech platform, and cloud provider is claiming to have AI capabilities. But there’s a fundamental architectural flaw in how virtually every one of them applies AI — and it’s a problem that has significant consequences for your costs, your security, and your risk posture.

With our new release of X1 Enterprise v6, we’ve built a genuinely different approach. Last week, our team hosted a live product tour to walk through what that looks like in practice. Here’s a summary of what we covered — and why I believe it changes everything.

The Problem: AI Is Being Applied Too Late
The eDiscovery and data governance workflow has been largely the same for over 20 years: Identify → Collect → Process → Host → Review. Every major vendor with AI capabilities today is applying AI at the very end of that process — at the Review stage — after data has already been moved or copied into their platform.

That’s too late. And it’s not just where they’re applying AI in the workflow — it’s how they’re applying it that’s the real problem.

Before AI ever touches your data in these platforms, you’ve already:
• Copied and transferred sensitive enterprise information to a vendor-controlled environment
• Paid for processing and hosting on the full data volume — including everything that turns out to be irrelevant
• Created security and compliance exposure from that mass data transfer to a third party
• Waited through long, throttled ingestion cycles before any analysis can begin

And now you’re being up-charged for ‘new’ AI capabilities on top of already expensive collection, hosting, and review fees. And the reason why you are being charged so much is that many of these vendors are merely brokering usage (and being charged for it) through large, centralized AI platforms.

If you’re considering pointing a cloud LLM — Claude, Copilot, ChatGPT, or even legal-focused platforms like Harvey — directly at your enterprise data to solve this problem, I want to be direct: they’re the wrong tool for the job. Cloud AI platforms cannot search data in-place. If you try to use them across your full enterprise data estate, you’ll be exfiltrating enormous volumes of data to their AI engines and consuming a massive number of tokens — exploding your costs in the process.

Infographic illustrating X1's approach to applying AI at the source before data moves, featuring steps: Identify, Collect, Process, Host, and Review.

X1’s Answer: AI In-Place, Before Anything Moves
X1 Enterprise v6 takes a fundamentally different architectural approach. We call it AI In-Place.

Rather than copying data into a centralized platform and then applying AI, X1 deploys distributed micro-indexes directly across your enterprise data sources — your M365 environment, endpoints, cloud repositories, and more. Your data stays exactly where it lives. We bring the AI to the data. Not the other way around.

That means AI decisioning happens before collection, before review-set creation, before any exporting, and before anything moves. We apply AI at the very beginning of the eDiscovery and data governance workflow — not at the end.

X1’s AI capabilities are about upstream AI enablement, not (yet another) prompt-wrapper that brokers expensive queries to Anthropic or OpenAI like too many other eDiscovery and Compliance Platforms. X1’s fundamental architectural shift means X1 neither charges nor incurs OEM AI costs, as the models are frozen and deployed in-place. This factor alone results in massive cost savings and efficiencies.

Infographic comparing two data architectures: 'Collect-First' process showing bulk copy and transfer methods, and 'Analyze-In-Place' by X1 featuring AI capabilities for data analysis in real-time.

One Platform, Across Every Critical Use Case
The AI In-Place architecture isn’t a point solution. It’s an enterprise platform that spans your most critical data workflows:

eDiscovery — X1 enables index-in-place early case assessment, data identification, and highly targeted collection. You get full data visibility and AI-powered responsiveness scoring before a single document is exported, resulting in dramatically smaller review volumes and lower costs — beginning before collection even starts.

Risk and Compliance — X1 identifies and remediates PCI, PII, and privacy-regulated data across your enterprise, continuously and without moving it into a compliance platform. It supports departed employee workflows, GDPR, FOIA, HIPAA compliance, and more — all analyzed and remediated in-place.

InfoSec and Investigations — When a breach occurs or an insider threat is suspected, time is critical. X1 gives investigation teams real-time capability at petabyte scale, across endpoint and cloud environments simultaneously — something no centralized architecture can match.

Information Governance — X1 handles large-scale data separation for M&A due diligence and divestitures, ROT analysis, records management policy enforcement, data mapping, and more — all in-place without migration or centralized data processing.

A Hidden Cost Nobody Is Talking About: Enterprise-Wide Token Explosion
There’s another dimension to this problem that rarely gets discussed openly, and it has major financial implications for any organization deploying AI at scale.

AI productivity tools like Claude or Copilot are genuinely valuable for administrative and day-to-day workflows — drafting emails, summarizing meetings, and generating content. But they are fundamentally the wrong tool for enterprise-wide data discovery.

Here’s why:

When you ask a cloud AI platform to find information across your enterprise data, it has no index to work from. It must retrieve and read the actual documents — potentially thousands or millions of them — just to locate what you’re looking for. Every document pulled into context consumes tokens. Every search, every query, every time someone asks a question about your data, the AI is ingesting enormous volumes of content to produce an answer. At enterprise scale, this doesn’t just add up — it explodes.

The costs compound quickly. Token pricing is consumption-based, and when your AI tool is reading entire document sets on every query rather than looking up a precise answer, you are essentially paying to re-read your entire data estate over and over again. For large organizations, this can translate into AI infrastructure costs that are orders of magnitude higher than they need to be.

X1’s local index-in-place technology solves this directly. Because X1 has already built a persistent, AI-enriched index across all your enterprise data sources — right where the data lives — your AI tools don’t need to go find and read the documents. Instead, the AI asks the question, X1 uses its index to identify the precise answer, and then delivers only the targeted files, documents, or data points the AI or end user actually needs. The documents themselves never have to be ingested into the AI platform at all.

The result is dramatically lower token consumption across your organization — because you’re sending the AI targeted answers, not raw document libraries. X1 becomes the intelligent retrieval layer that makes your existing AI investments far more efficient and far less expensive to operate at scale.

Where We’re Headed: X1 as the Governed Retrieval Layer for Enterprise AI
As your organization deploys more AI assistants and agents — through Copilot, Claude, or internal AI tools — they will all need a secure, governed way to retrieve knowledge from your distributed data. X1 is being built to serve as that infrastructure layer that connects your AI tools to your data.

Our vision is for X1 to become the MCP Server for your LLMs — the governed retrieval layer that sits between your centralized AI systems and your enterprise data. Your AI tools will ask the questions. X1 will find and provide the answers — safely, compliantly, at scale, with minimal cost, and without data ever leaving its source.

Three Things I Want You to Take Away

  1. AI In-Place gives you a real strategic advantage. Security, speed, and scalability — at a fraction of the cost — with your data never leaving your environment. There’s no need to collect, move, copy, re-index, or centralize before analysis can begin. The shortest path to insight is leaving the data where it already is.
  2. We will never monetize your data. Full stop. You can analyze your data in place and pay nothing extra for the AI capabilities we’ve built into v6. No data charges. No add-on fees. Ever. Your data is an asset — it shouldn’t be a revenue stream for your software vendor.
  3. Control belongs with you. This industry has been charging customers a premium for over-collection, over-processing, bloated hosting, inefficient review, and now AI add-on fees on top of it all. That model ends here. X1’s AI-native approach cuts through it entirely — dramatically lower costs, no unnecessary data sprawl, and control back where it belongs.

If you missed the webinar, you can watch it now here. And if you’d like to see what AI In-Place looks like in your specific environment — your M365 footprint, your eDiscovery program, your compliance posture — reach out to us at info@x1.com or visit x1.com to schedule a private demo.

“The right architecture for AI isn’t about moving your data to the AI. It’s about bringing the AI to your data.”
— Larry Gill, CEO, X1 Discovery

Leave a comment

Filed under Best Practices, Cloud Data, Corporations, Cybersecurity, Data Audit, Data Governance, ECA, eDiscovery & Compliance, Enterprise AI, Enterprise eDiscovery, ESI, GDPR, Information Governance, Information Management

Why X1’s AI In-Place Architecture Is a Genuine Departure from Legal AI’s Status Quo

By John Patzakis

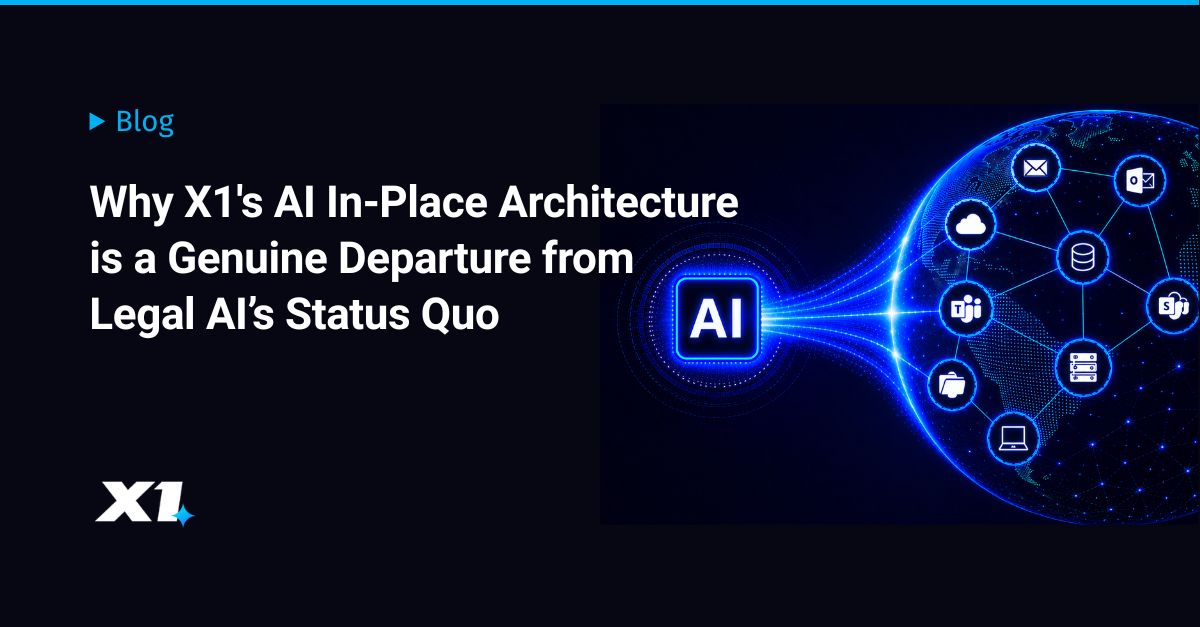
X1 AI In-Place Architecture — AI hub connecting to distributed enterprise data sources including Microsoft 365, email, cloud, and endpoints

The legal technology market has a buzzword problem. Terms like “AI-powered,” “intelligent review,” and “automated analysis” have been applied so broadly—and so inconsistently—that they have largely lost their ability to signal anything meaningful about how a product actually works. Against that backdrop, X1’s announcement last week of AI In-Place for X1 Enterprise represents a genuinely different approach to applying AI within enterprise legal and compliance workflows. The reason for this basis is X1’s unique architecture.

To understand why, it helps to start with the dominant model that most legal AI tools share. The overwhelming majority of AI-enabled eDiscovery and governance platforms are built on a collect-first assumption: data must be moved out of its native environment—copied, ingested, centralized in a vendor-controlled repository—before any AI model can be applied to it. This is not an incidental design choice; it reflects the fundamental architecture of how most of these platforms were built, long before AI became part of the product story. The result is what practitioners have come to call the “prompt wrapper” problem: an AI interface sits in front of a conventional data pipeline, and the underlying mechanics—the cost, the risk, the latency—remain largely unchanged. A large language model with a “middleware” workflow does not solve the structural problem of what happens to sensitive data before the AI touches it.

X1’s AI In-Place architecture inverts that assumption. Rather than requiring data to travel to an AI system, X1’s patented distributed micro-indexing technology deploys AI models directly into lightweight micro-indexes at the data source itself—across Microsoft 365 environments, file shares, cloud repositories, and endpoints. The AI executes where the data lives, and the data does not move. The implications run across multiple dimensions: data never leaves the enterprise perimeter, security policies and endpoint controls remain intact throughout the process, and the computational overhead and massive AI token costs associated with large-scale data ingestion is avoided entirely. For matters involving a terabyte of data or more—where centralized collection is not merely expensive but operationally infeasible—this architectural distinction is not incremental. It changes what is actually possible.

The workflow mechanics reinforce the point. AI models are deployed into X1’s distributed micro-indexes behind the firewall, execute against enterprise data in place, and surface AI-enriched insights—tags, classifications, risk scores—into a central console without the underlying data ever being collected or copied. That means targeted collection decisions, early case assessment, and information governance actions can be driven by AI-informed analysis conducted across the full enterprise data landscape, not just against a subset of data that has already been moved. The distinction matters because the scope of analysis in the collect-first model is constrained by collection costs; in the in-place model, analysis scope is no longer tethered to collection volume. Investigations and governance programs can, in principle, cast a much wider net analytically while actually reducing the volume of data that requires review.

Mandi Ross, CEO of Insight Optix, offered a perspective that cuts to the core of what makes this architecture commercially significant: “Enabling AI directly where the clients’ data resides fundamentally changes the economics, speed, and risk profile of enterprise data discovery, investigations and compliance workflows. With X1 Enterprise AI In-Place, we can deploy AI models, pre-trained or customized for specific matters, data queries, or compliance requirements—securely within client environments, dramatically accelerating time to insight without sensitive information being collected, duplicated, or centralized outside their control.”

Ross identifies three dimensions the in-place approach changes: economics, speed, and risk. On economics, a significant lever is the reduction in review population size—AI-informed pre-collection filtering means fewer documents proceed to human review. Additionally, costs associated with collection and processing, including expensive AI token utilization, are all but eliminated. On speed, running analysis in situ, without waiting for collection and ingestion cycles, compresses time to first insight—critical in time-sensitive investigations and regulatory responses. On risk, data that does not move cannot be breached in transit, does not reside in vendor infrastructure outside the client’s control, and does not generate the compliance exposure of large-scale cross-boundary transfers. Her comment reflects what experienced practitioners understand but marketing language tends to obscure: the most consequential question about any legal AI tool is not what the AI does, but what happens to the data before and during its operation.

The enterprise deployment model reflects design discipline that distinguishes AI In-Place from retrofitted solutions. Organizations retain centralized governance over AI usage while processing remains local under existing security policies and endpoint controls. AI capabilities are fully optional and configurable at the data source level—important for organizations operating across multiple jurisdictions with differing regulatory requirements—and customer data is never used to train, fine-tune, or enrich underlying AI models, addressing a standard due diligence concern in enterprise AI procurement.

The practical use case implications are significant across several domains. In legal and eDiscovery contexts, in-place TAR and pre-collection analytics allow AI-informed decisions about what to collect before collection begins, directly reducing review volumes and costs. In information governance, AI-driven classification and policy enforcement can operate continuously across the full enterprise data estate rather than against periodic snapshots, enabling more responsive and defensible governance programs. In security and investigations, real-time insider risk detection at petabyte scale—across endpoint and cloud environments simultaneously—becomes feasible where centralized architectures make it impractical. In each case, analytical scope is no longer constrained by collection logistics.

Most legal AI products apply AI to data after it has already moved through the conventional collection pipeline. AI In-Place asks a more fundamental question: whether the pipeline itself should be reconceived. We will demonstrate it live on Wednesday, June 24—for those evaluating enterprise AI in legal, compliance, or governance contexts, it is worth seeing what a genuinely different architecture looks like in practice.

Register for the June 24 AI In-Place™ Product Tour →

Leave a comment

Filed under Best Practices, Cloud Data, Corporations, Cybersecurity, Data Audit, Data Governance, ECA, eDiscovery & Compliance, Enterprise AI, Enterprise eDiscovery, Enterprise Search, ESI, GDPR, Information Access, Information Governance, Information Management, m365, MS Teams, OneDrive, SharePoint