Category Archives: OneDrive

Purview’s Limits Are Your Cost and Risk Problem

By Chas Meier

Last week, John Patzakis explained why Microsoft Purview eDiscovery is getting worse and why the reasons are structural: a multi-tenant architecture that must throttle heavy workloads, a 2 GB per hour indexing ceiling that has not moved since 2024, no service level commitment for search times, and a finite pool of compute that Microsoft has told investors it allocates to its highest-value opportunities, with Copilot first in line.

That post was about the cause. This one is about the consequence, and it is a consequence that reaches well beyond legal operations. When the tool at the front of your eDiscovery workflow cannot filter reliably, the organization’s answer is almost always the same: collect everything and sort it out later. Every gigabyte that leaves your environment that way is a gigabyte you pay to process, host and review, and a gigabyte that now sits somewhere you do not control, at exactly the moment attackers are becoming faster and better equipped than they have ever been.

The argument below is simple. Purview’s limits drive over-collection. Over-collection drives cost. Cost and copies drive risk. And the risk curve is about to steepen.

When Filtering Fails, Over-Collection Becomes the Default
In principle, Purview lets you search before you collect. In practice, the service providers and enterprise teams we speak with tell us that targeted collection in Purview has become something they plan around rather than rely on.

  • Searches stall or time out.
  • Indexing runs at 2 GB per hour, so a 500 GB custodian set takes more than ten days to index before a search can be trusted.
  • Partially indexed items that exceed parsing limits quietly fall outside keyword results.
  • Exports are capped at 2 GB per hour per mailbox with daily tenant-level limits, and anything still running after seven days is cancelled.

Faced with a deadline and a toolset that cannot be trusted to narrow the data defensibly, legal teams do the rational thing: they widen the net. Rather than risk a motion over an under-inclusive search, they pull entire mailboxes, entire OneDrive accounts, entire Teams channels, and push the filtering downstream to a processing platform or a service provider where the tools actually work. One provider described it to us as “collect the custodian, not the matter.”

This is not a failure of judgment by the legal team. It is the predictable response to a collection tool that cannot do its job at enterprise scale. But it means that the single most effective cost and risk control in eDiscovery, culling data before it ever leaves the enterprise, is being abandoned at the very step where it matters most.

Not a Purview User? You Probably Are One Anyway
Many organizations read our Purview posts and conclude they do not apply because the legal team never logs into the Purview portal. They use a service provider, or a collection toolkit from their review platform vendor, or a connector that “just pulls from Microsoft 365.” That conclusion is usually wrong.

Look under the hood of most Microsoft 365 collection workflows and you find Purview. Many third-party connectors and service provider toolkits are built on Microsoft’s eDiscovery search and export APIs, which means they inherit the same index, the same 2 GB per hour ceilings, the same tenant-level export caps and the same throttling. Some tools run a Purview search and export in the background and present the result in their own interface. Others collect whole mailboxes through Graph or EWS precisely because the Purview search path is too slow and unreliable to filter with, which is over-collection by design. Either way, Purview’s limitations are shaping what gets collected from your tenant, even if nobody on your team has ever opened it.

If you are not sure which category your workflow falls into, that is worth finding out. Ask your provider or your platform vendor two questions:

  1. Does your Microsoft 365 collection depend on Purview’s index or Microsoft’s eDiscovery APIs?
  2. What percentage of the data you collect from our tenant is ultimately produced?

If the first answer is yes and the second answer is in the low single digits, you are an indirect Purview user, and you are paying for it.

The Volume Does Not Disappear. It Moves Downstream.
Data that is not filtered at collection does not go away; it flows into the next stage of the workflow. Whole-custodian collections land on a service provider’s processing infrastructure or in a hosted review platform, where the filtering that should have happened inside the enterprise is finally performed, at a per-gigabyte price. The industry has become very good at absorbing that volume, which is part of why the problem is so easy to ignore. Processing gets faster, hosting gets cheaper per unit, and analytics get better at culling. But none of that changes the fact that the data has already left.

The numbers compound quickly:
• A matter with 20 custodians and an average of 30 GB per custodian across email, OneDrive and Teams produces 600 GB of exfiltrated data before a single document has been reviewed.
• A targeted in-place search would have narrowed that to 5%; the other 570 GB is pure overhead: ingested, processed, deduplicated, and hosted for the life of the matter, and then for years afterward.
• Multiply that across every matter, investigation and regulatory request in a year and the over-collection tax on a mid-size enterprise runs into the hundreds of thousands of dollars, and for a large one, well into the millions.

Service providers see the other side of this. Their platforms are filling with data that nobody needed, and their clients are increasingly asking why the processing and hosting line items keep growing when case counts are flat. The honest answer: the collection tool upstream stopped doing its job.

Every Exfiltrated Gigabyte Is Both a Cost and a Risk
The cost side is visible on the invoice. Processing, hosting, review, productions and long-tail storage all scale with volume, and over-collection inflates every one of them. What is harder to see is that the same volume is also the organization’s single largest self-inflicted security exposure.

Consider what an eDiscovery collection actually is: a curated copy of your most sensitive communications, deliberately assembled, stripped of the access controls that protected it in the source system, and shipped to a third party. Executive email. Board materials. Privileged legal advice. Customer data, employee data, trade secrets, M&A deliberations. A whole-custodian collection does not just include the documents relevant to the matter; it includes everything that custodian ever touched. And it is now sitting on a service provider’s processing server, in a hosted review platform, in a law firm’s document management system, on an export drive, and in whatever backups each of those parties keeps.

Each copy is a new attack surface governed by someone else’s security program, someone else’s patch cycle and someone else’s employees. Law firms and eDiscovery vendors are high-value targets precisely because they aggregate the crown jewels of many clients in one place, and the breach record of the last several years bears that out. When one of those copies is compromised, the breach notification obligations, regulatory exposure and reputational damage belong to you, not to the vendor, and they attach to all of the data that was collected, not just the small fraction that was ever relevant.

Over-collection, in other words, turns a legal cost problem into an enterprise security problem. The 95% of the collection that was never responsive was never worth that risk.

The Next 12 to 24 Months: AI on the Other Side of the Wall
If the risk calculus above were static, over-collection might be a tolerable inefficiency. It is not static. The same generative AI wave that is consuming Microsoft’s compute capacity is also arming the people who want your data.

AI has collapsed the cost and skill required to run a sophisticated attack. Phishing campaigns are now fluent, personalized and generated at scale. Vulnerability discovery and exploit development that once took skilled teams weeks can be accelerated by models that reason over code. Reconnaissance against a target’s vendors, employees and infrastructure is automated. Agentic tooling allows a single operator to run many intrusion attempts in parallel and adapt to defenses in real time. Security researchers and government agencies have been warning for the past year that AI-enabled intrusion is moving from proof of concept to routine practice, and the trend lines for breach frequency, ransomware payouts and time-to-exploit all point the same way.

Over the next 12 to 24 months, we expect frequent, aggressive and automated attacks to become the baseline rather than the exception, and we expect the organizations that aggregate other companies’ sensitive data, including eDiscovery service providers, review platforms and law firms, to remain among the most attractive targets. Vendors will keep investing in defenses. But a defender has to be right every time, and AI has made the attacker’s job dramatically cheaper.

The only exposure you fully control is the amount of data you send out in the first place. Every copy you do not create is a copy that cannot be breached.

Now Is the Time to Be Proactive
The organizations that will be in the strongest position two years from now are the ones that treat eDiscovery collection as a data governance and security decision, not just a legal workflow step. That means three things.

  • Limit exfiltration. Search, cull and validate inside your own environment, and collect only what is potentially responsive. The goal is to move the filtering step back to where it belongs, before the data leaves, so that what reaches a provider or a review platform is the matter, not the custodian.
  • Limit unnecessary cost. Every gigabyte you keep inside the enterprise is a gigabyte you do not pay to process, host, review and store. Targeted in-place collection is the single largest lever available to reduce eDiscovery spend, and it is a lever that most Microsoft 365 organizations are not currently pulling because their tooling does not let them.
  • Remain in control of your data. Run eDiscovery and governance on infrastructure you control, with search methodology you can test and document, indexes you own, and no dependence on a shared tenant’s throttling policies or a cloud provider’s capacity priorities. Control means being able to answer a court, a regulator or a board with confidence about what you searched, what you collected and where it went.

Waiting for Purview to improve is not a strategy. Last week’s post explained why its limitations are architectural and why Microsoft’s own capacity constraints make relief unlikely. Meanwhile the cost of over-collection accrues on every matter, and the risk of each unnecessary copy grows with every advance in offensive AI. The time to change the workflow is before the next large matter, not after the next breach.

How X1 Enterprise Is Different
X1 Enterprise was built for exactly this problem: search and collect in place, so that only what matters ever leaves. The differences from a Purview-dependent workflow are architectural, not cosmetic.

In-place indexing you own. X1’s patented distributed micro-indexing technology indexes Microsoft 365 data where it lives, across Exchange, OneDrive, SharePoint and Teams, alongside endpoints, file shares and other cloud sources. X1 does not use Purview’s index or Microsoft’s eDiscovery search APIs, so there is no 2 GB per hour ceiling, no tenant-level export cap, no seven-day cancellation and no throttling inherited from every other tenant on the platform.

Compute you control. X1 runs on infrastructure the customer controls, on premises or in the customer’s own cloud. Your eDiscovery and governance jobs are never queued behind Copilot or anyone else’s workload, and performance is predictable because it is yours.

Search that meets the courts’ standard. Full Boolean, proximity, wildcard and stemming queries execute consistently across email, files and Teams chat, with the ability to iteratively test, refine, validate and document search methodology before anything is collected. That is the “advanced and thoughtful” search the Kim v. Cushman & Wakefield court said Teams data requires, and the validation Special Master Favro found missing in native Microsoft 365 tools.

Targeted collection, not whole-custodian export. Because the search runs in place and can be trusted, only potentially responsive data is collected. Filtering moves back to the front of the workflow, where it cuts downstream volume, cost and exposure at the source. Collected data can be uploaded directly into Relativity for review.

Defensibility by design. Preservation, search and collection are logged and reportable, so you can show a court or a regulator exactly what was searched, when, with what criteria, and what was collected.

AI where the data lives. The same in-place architecture powers X1 AI In-Place, allowing organizations to apply AI classification directly to data in its source location for early case assessment, privilege and sensitivity identification, and information governance, again without exporting the data to do it.

Talk With X1
If your Microsoft 365 collections are coming back as whole custodians, if your processing and hosting invoices keep growing while your case count does not, or if you have never asked how much of the data you send out is actually responsive, we would like to talk.

Contact X1 to schedule a live demonstration of X1 Enterprise against a Microsoft 365 environment. Better still, bring us a recent matter. We will run a targeted in-place search on your own data and show you how much volume, cost and risk you could have kept inside the enterprise.

The next large matter is coming, and so is the next wave of attacks. Collect less, spend less and keep control of your data.
Leave a comment

Filed under AI In-Place, Best Practices, Cloud Data, Corporations, Cybersecurity, Data Governance, ECA, eDiscovery, eDiscovery & Compliance, Enterprise AI, Enterprise eDiscovery, ESI, GDPR, Information Governance, Information Management, m365, MS Teams, OneDrive

Why X1’s AI In-Place Architecture Is a Genuine Departure from Legal AI’s Status Quo

By John Patzakis

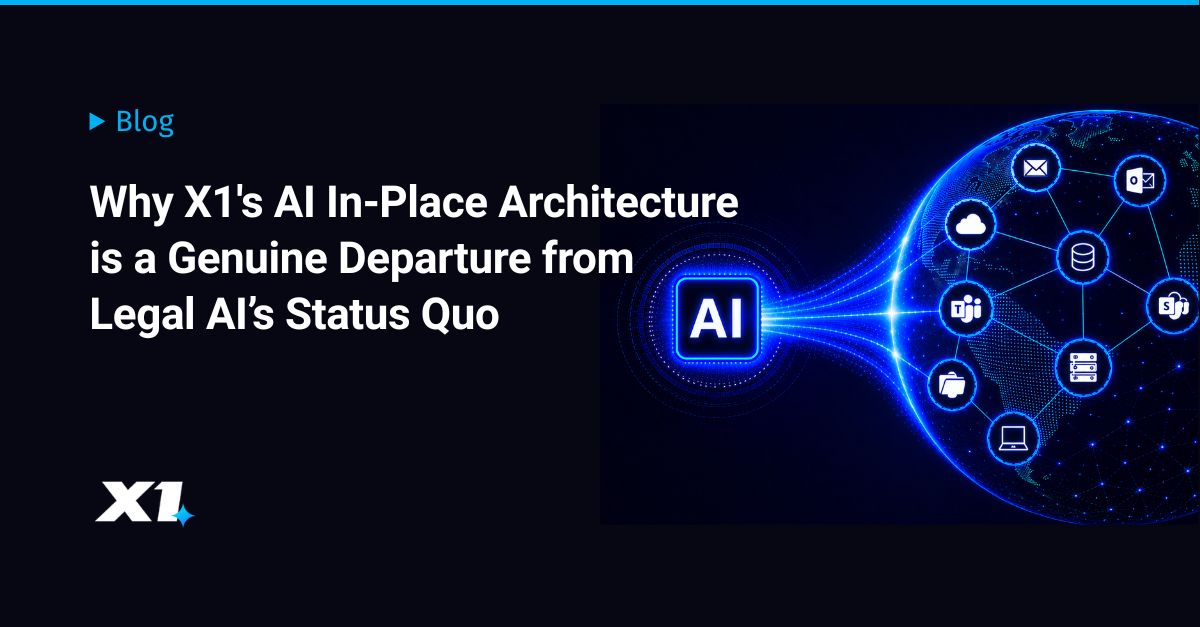
X1 AI In-Place Architecture — AI hub connecting to distributed enterprise data sources including Microsoft 365, email, cloud, and endpoints

The legal technology market has a buzzword problem. Terms like “AI-powered,” “intelligent review,” and “automated analysis” have been applied so broadly—and so inconsistently—that they have largely lost their ability to signal anything meaningful about how a product actually works. Against that backdrop, X1’s announcement last week of AI In-Place for X1 Enterprise represents a genuinely different approach to applying AI within enterprise legal and compliance workflows. The reason for this basis is X1’s unique architecture.

To understand why, it helps to start with the dominant model that most legal AI tools share. The overwhelming majority of AI-enabled eDiscovery and governance platforms are built on a collect-first assumption: data must be moved out of its native environment—copied, ingested, centralized in a vendor-controlled repository—before any AI model can be applied to it. This is not an incidental design choice; it reflects the fundamental architecture of how most of these platforms were built, long before AI became part of the product story. The result is what practitioners have come to call the “prompt wrapper” problem: an AI interface sits in front of a conventional data pipeline, and the underlying mechanics—the cost, the risk, the latency—remain largely unchanged. A large language model with a “middleware” workflow does not solve the structural problem of what happens to sensitive data before the AI touches it.

X1’s AI In-Place architecture inverts that assumption. Rather than requiring data to travel to an AI system, X1’s patented distributed micro-indexing technology deploys AI models directly into lightweight micro-indexes at the data source itself—across Microsoft 365 environments, file shares, cloud repositories, and endpoints. The AI executes where the data lives, and the data does not move. The implications run across multiple dimensions: data never leaves the enterprise perimeter, security policies and endpoint controls remain intact throughout the process, and the computational overhead and massive AI token costs associated with large-scale data ingestion is avoided entirely. For matters involving a terabyte of data or more—where centralized collection is not merely expensive but operationally infeasible—this architectural distinction is not incremental. It changes what is actually possible.

The workflow mechanics reinforce the point. AI models are deployed into X1’s distributed micro-indexes behind the firewall, execute against enterprise data in place, and surface AI-enriched insights—tags, classifications, risk scores—into a central console without the underlying data ever being collected or copied. That means targeted collection decisions, early case assessment, and information governance actions can be driven by AI-informed analysis conducted across the full enterprise data landscape, not just against a subset of data that has already been moved. The distinction matters because the scope of analysis in the collect-first model is constrained by collection costs; in the in-place model, analysis scope is no longer tethered to collection volume. Investigations and governance programs can, in principle, cast a much wider net analytically while actually reducing the volume of data that requires review.

Mandi Ross, CEO of Insight Optix, offered a perspective that cuts to the core of what makes this architecture commercially significant: “Enabling AI directly where the clients’ data resides fundamentally changes the economics, speed, and risk profile of enterprise data discovery, investigations and compliance workflows. With X1 Enterprise AI In-Place, we can deploy AI models, pre-trained or customized for specific matters, data queries, or compliance requirements—securely within client environments, dramatically accelerating time to insight without sensitive information being collected, duplicated, or centralized outside their control.”

Ross identifies three dimensions the in-place approach changes: economics, speed, and risk. On economics, a significant lever is the reduction in review population size—AI-informed pre-collection filtering means fewer documents proceed to human review. Additionally, costs associated with collection and processing, including expensive AI token utilization, are all but eliminated. On speed, running analysis in situ, without waiting for collection and ingestion cycles, compresses time to first insight—critical in time-sensitive investigations and regulatory responses. On risk, data that does not move cannot be breached in transit, does not reside in vendor infrastructure outside the client’s control, and does not generate the compliance exposure of large-scale cross-boundary transfers. Her comment reflects what experienced practitioners understand but marketing language tends to obscure: the most consequential question about any legal AI tool is not what the AI does, but what happens to the data before and during its operation.

The enterprise deployment model reflects design discipline that distinguishes AI In-Place from retrofitted solutions. Organizations retain centralized governance over AI usage while processing remains local under existing security policies and endpoint controls. AI capabilities are fully optional and configurable at the data source level—important for organizations operating across multiple jurisdictions with differing regulatory requirements—and customer data is never used to train, fine-tune, or enrich underlying AI models, addressing a standard due diligence concern in enterprise AI procurement.

The practical use case implications are significant across several domains. In legal and eDiscovery contexts, in-place TAR and pre-collection analytics allow AI-informed decisions about what to collect before collection begins, directly reducing review volumes and costs. In information governance, AI-driven classification and policy enforcement can operate continuously across the full enterprise data estate rather than against periodic snapshots, enabling more responsive and defensible governance programs. In security and investigations, real-time insider risk detection at petabyte scale—across endpoint and cloud environments simultaneously—becomes feasible where centralized architectures make it impractical. In each case, analytical scope is no longer constrained by collection logistics.

Most legal AI products apply AI to data after it has already moved through the conventional collection pipeline. AI In-Place asks a more fundamental question: whether the pipeline itself should be reconceived. We will demonstrate it live on Wednesday, June 24—for those evaluating enterprise AI in legal, compliance, or governance contexts, it is worth seeing what a genuinely different architecture looks like in practice.

Register for the June 24 AI In-Place™ Product Tour →

Leave a comment

Filed under Best Practices, Cloud Data, Corporations, Cybersecurity, Data Audit, Data Governance, ECA, eDiscovery & Compliance, Enterprise AI, Enterprise eDiscovery, Enterprise Search, ESI, GDPR, Information Access, Information Governance, Information Management, m365, MS Teams, OneDrive, SharePoint

X1 Expands Its Leadership in Microsoft Teams eDiscovery Collection

X1 Enterprise MS Teams Collection

By John Patzakis and Chas Meier

The rapid growth of Microsoft 365 has fundamentally changed the eDiscovery landscape. Among its most prominent data sources, Microsoft Teams now generates vast volumes of business-critical communications that must be identified, collected, and reviewed in litigation, regulatory, and compliance matters.

Yet most eDiscovery tools still rely on outdated methods: bulk copying massive amounts of sensitive data and transferring it to proprietary processing or review platforms. This approach is slow, costly, and disruptive. Bulk transfers frequently trigger Microsoft’s throttling controls, adding significant delays. More importantly, organizations that have invested heavily in Microsoft 365 do not want their data routinely exported out of its secure, native environment every time an eDiscovery matter or compliance investigation arises.

Recognizing these challenges, X1 has built upon its industry-leading Microsoft 365 collection capabilities to deliver unmatched support for Microsoft Teams—alongside OneDrive, Exchange, and SharePoint.

Key Benefits of X1’s Teams Collection Capabilities
• Precision targeting of Channels at scale – Quickly search all available channels, select, and target specific Teams channels, even in organizations with tens of thousands of them. This feature is not even available in Microsoft Purview!
• Granular control – Target individual custodians and message threads, avoiding unnecessary mass downloads.
• Contextual collections – Automatically include a designated number of preceding and subsequent messages, preserving conversational context.
• Seamless review integration – One-click upload of fully formatted in-context results directly into review platforms—no manual processing required.
• Unified approach – Search and collect across Teams, OneDrive, SharePoint, Exchange, laptops, and file shares from a single interface.
• In-place indexing – Leverage X1’s patented technology to index, search, and process data where it resides, eliminating reliance on expensive third-party processing.
• True automation – A software-based solution that reduces dependency on manual, service-heavy workflows.

No other independent software provider matches the speed, precision, and scalability of X1’s Microsoft Teams eDiscovery collection. Our customers consistently report significant gains in efficiency, cost savings, and defensibility compared to legacy approaches.

As Teams usage continues to surge, legal and compliance professionals need solutions that deliver targeted, defensible collections without the inefficiencies of bulk exports. X1’s enhanced Teams support ensures organizations can meet these demands with speed, accuracy, and minimal disruption.

Seeing is believing—watch our short demo video to experience X1’s Teams capabilities in action.

Leave a comment

Filed under Best Practices, Cloud Data, Corporations, ECA, eDiscovery, eDiscovery & Compliance, Enterprise eDiscovery, Enterprise Search, ESI, Hybrid Search, Information Governance, m365, MS Teams, OneDrive

X1 Achieves Record Growth as Numerous Fortune 500 Companies Standardize on X1 Enterprise

By Larry Gill

X1 Discovery is having a record-breaking year, with dozens of Fortune 500 companies and leading law firms adopting the X1 Enterprise Platform to transform how they approach eDiscovery collection, early case assessment, and information governance. In an era when overcollection and skyrocketing legal costs strain corporate budgets, these organizations are choosing X1 to gain immediate insight into their data, dramatically reduce costs, and ensure defensible, repeatable processes—all while maintaining complete control over their information. This surge in adoption reflects X1’s position as the industry’s trusted solution for modern, efficient, and targeted enterprise eDiscovery.

The X1 Enterprise Platform is an industry-leading eDiscovery and information governance solution that empowers organizations to search, identify, analyze, and act on their data in-place, wherever it resides. X1 uniquely addresses Microsoft 365—including robust Teams support—laptops, file servers, and other cloud and on-premises sources, giving legal and compliance teams unparalleled reach and control. Dozens of major enterprises and AM Law 100 firms have now standardized on X1, recognizing it as the most effective solution for managing M365 content—often outperforming even Purview Premium—while also covering on-premises data sources seamlessly. By enabling a highly targeted, efficient, index-in-place approach, X1 provides immediate, pre-collection visibility, streamlining search, analysis, remediation, and collection workflows like never before.

Here are the top three reasons why leading organizations are adopting X1 Enterprise in record numbers:

  1. Significant Return on Investment
    Corporate legal departments that implement X1 consistently realize up to 90% in “hard” cost savings. X1’s powerful in-place search and pre-collection filtering enable teams to collect only what is needed, achieve true proportionality, and eliminate massive outsourced processing and project management fees. Many organizations are even scaling back or eliminating costly Purview Premium licenses altogether, all while mitigating risk with a defensible and repeatable collection process.
  2. Unmatched Speed and Scalability
    X1 delivers speed and scalability that no other solution can match. It can search across thousands of laptops and multiple terabytes of M365 or file share data within minutes, quickly pinpointing responsive data for precise collection or remediation. All indexed data stays securely behind the corporate firewall or in a private cloud. Unlike legacy tools that overpromise and underdeliver, X1 is proven to work and scale as advertised, backed by real-world case studies and customer success stories.
  3. Multiple Use Cases Beyond eDiscovery
    Beyond eDiscovery, corporate legal and compliance teams leverage X1 to locate and remediate sensitive personal information (PII), defensibly purge redundant or non-compliant data, support due diligence and data separation during M&A transactions, and handle GDPR Data Subject Access Requests (DSARs) and other data privacy obligations—making X1 a true multipurpose platform for enterprise information governance.

In today’s data-driven world, X1 Enterprise is more than a solution—it’s a strategic advantage. For organizations serious about controlling eDiscovery costs, reducing risk, and gaining immediate insight into their data, X1 is the clear choice.

Interested in learning more about how to dramatically reduce your costs and compliance risks? Schedule a briefing today at sales@x1.com or visit www.x1.com/solutions/x1-enterprise-platform.

Leave a comment

Filed under Authentication, Cloud Data, Corporations, Cybersecurity, Data Audit, eDiscovery, eDiscovery & Compliance, Enterprise eDiscovery, ESI, GDPR, Information Access, Information Governance, m365, MS Teams, OneDrive, Preservation & Collection, SharePoint

X1 Search Version 10: A Game-Changer for Modern Enterprise Search

By John Patzakis

Enterprise search has long been a pain point for organizations—fragmented data, slow retrieval, and outdated architectures have left businesses struggling to find information efficiently, resulting in millions of hours of lost productivity. But with the release of X1 Search Version 10, a new era has arrived—one that redefines how business professionals search, discover, and act on their information across cloud and endpoint ecosystems.

And the standout features? Full integration with Slack, enhanced support for Microsoft 365, support for Gmail and Google Drive and numerous other cloud data sources, as well as improvements to our enterprise-grade speed and scalability! With version 10, you can now search Slack in tandem with your email, files, and your Microsoft 365 data sources, including Teams.

Slack and Teams have become the modern enterprise’s water cooler and meeting room rolled into one. It is where you and your colleagues have critical conversations, exchange files, and document decisions. But until now, most enterprise search tools could not index Slack effectively, let alone allow unified searching across Slack and email.

X1 Search 10 changes the game by uniquely enabling real-time search across Slack messages, channels, and attachments alongside your Outlook, M365, Google Workspace, files, and more—all in a single interface. This allows business professionals to instantly search all their key information and full context of communication threads, no matter where their conversations took place. Imagine searching, seeing, and acting on your relevant Slack chats, Teams chats, email threads, and related documents side by side, in seconds. No toggling between systems. No data blind spots. Just instant insight and supercharged productivity.

Speed, Scale, and Simplicity with Micro-Indexing
What makes this lightning-fast and massively scalable experience possible is X1’s patented search and micro-indexing architecture. Unlike legacy systems that first require inefficient, time-consuming crawlers to collect, duplicate, and then transfer the data en masse into central repositories, which is a recipe for failure, X1 indexes data in-place. This means:

• No massive data movement
• Real-time indexing at the source
• Full maintenance of user permissions and access controls
• Lightning-fast search response times—even across multi-terabyte datasets

This distributed, index-in-place model is purpose-built for today’s data environment, where critical content lives across cloud platforms (Microsoft 365, OneDrive, SharePoint, Slack), endpoints, MS Exchange Servers, and file shares. With X1, organizations get a true federated view of enterprise content—without sacrificing speed, security, information governance, or user experience.

Legacy Enterprise Search Is Officially Obsolete
Traditional enterprise search tools—built for centralized environments—are no match for the demands of the modern workplace. As data continues to fragment across cloud platforms, remote endpoints, and collaboration apps like Slack and Teams, the old Enterprise Content Management (ECM) model of copy and migration to centralized indexing is completely untenable in terms of the laws of physics as well as creating significant security and governance risks.

X1 Search leapfrogs past those outdated architectures. With native support for Slack, robust Microsoft 365 integration, and enterprise-grade security and scalability, X1 enables rapid search and collection across the full digital workplace.

No more hours of lost productivity per week. Just real-time, precise search across your enterprise data—wherever it lives.

X1 Search Version 10 is now available. Ready to see it in action? Watch a 4-minute demo or obtain a free trial license (no credit card required) now.

Leave a comment

Filed under Best Practices, Business Productivity Search, Cloud Data, Corporations, Desktop Search, Enterprise Search, Hybrid Search, Information Management, m365, MS Teams, OneDrive, productivity, Records Management, SharePoint, X1 Search 10